

Maximum of 25 job preferences reached.
Top Tech Jobs & Startup Jobs in Seattle, WA

Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Provide Tier 1 support for complex cloud platforms, troubleshoot distributed software and customer issues, investigate root causes, improve operational workflows, create runbooks and documentation, build support tooling, and coordinate with engineering, SRE, and other internal teams. The role supports production systems through an on-call rotation and requires expertise across cloud infrastructure, networking, storage, Kubernetes, Linux, and DevOps tooling, with GPU, MLOps, HPC, or SLURM experience preferred.
Top Skills:
AWSAzureBlob StorageBlock StorageDatabasesDevOpsDistributed Training SystemsFile StorageGoogle Cloud Platform (Gcp)Gpu WorkloadsHigh-Performance Computing (Hpc)InfrastructureKubernetesLinuxMachine Learning InfrastructureMlopsNetworkingOracle Cloud Infrastructure (Oci)SlurmStorage
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Develop CUDA-Q core infrastructure for inter-device communication and efficient execution across hybrid quantum-classical systems. Build extensible compiler toolchains integrating quantum architecture components, solve problems spanning compilers, high-performance computing, and quantum computing, and collaborate on software design. Improve development processes and infrastructure while delivering performant, robust production software.
Top Skills:
CudaCuda-QDistributed SystemsFpgaGpuHigh-Performance ComputingLlvmMlirQuantum Computing
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Design, deploy, maintain, tune, and secure enterprise Linux environments supporting high-performance EDA compute farms. Lead infrastructure-as-code automation, configuration management, continuous deployment, and tooling development using Python, Bash, or Go. Manage LDAP/SSSD naming services, NFS and Autofs storage, virtualization, container infrastructure, registries, networking, and infrastructure telemetry. Support highly available, scalable systems and potentially integrate cloud platforms, CI/CD pipelines, EDA toolchains, and HPC clusters.
Top Skills:
AnsibleAutofsAWSBashCadenceDockerGCPGithub ActionsGitlab CiGoInfrastructure As CodeJenkinsKubernetesLdapLinuxLsfMicrovmsNfsPodmanPythonRpm-Based Linux DistributionsSdnSlurmSssdSynopsysTcpdumpTerraformWireshark
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Design, deploy, operate, and automate reliable large-scale EDA infrastructure services on NVIDIA hardware. Build tools that reduce manual work, support distributed private and public cloud systems, define service-level objectives, improve observability, and participate in incident response and on-call rotations. The role also provides systems-design guidance to peer teams and may involve Kubernetes, OpenStack, Docker, Slurm, multi-cloud infrastructure, networking, storage, and GPU-based systems.
Top Skills:
Ai AgentsBare Metal As A ServiceCloud InfrastructureContainersContinuous IntegrationDistributed SystemsDockerGoInfrastructure AutomationKubernetesLinuxMcp ServersNetworkingNvidia GpusOpenstackPythonSlurmStorageWorkflow Engines
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Leads a distributed team securing NVIDIA DGX Cloud’s large-scale GPU infrastructure. Responsibilities include hiring and developing engineers, setting strategy for security control planes and foundational services, delivering measurable risk reduction, maintaining engineering standards, communicating security risks to executives, and collaborating with platform, SRE, networking, and security teams. The role requires strong engineering management, infrastructure or security expertise, cloud-native fluency, and influence across partner organizations.
Top Skills:
Cloud-Native ArchitectureDistributed SystemsGpu InfrastructureHigh-Performance ComputingIdentity And Access ManagementKubernetesPolicy EnforcementVulnerability Management
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free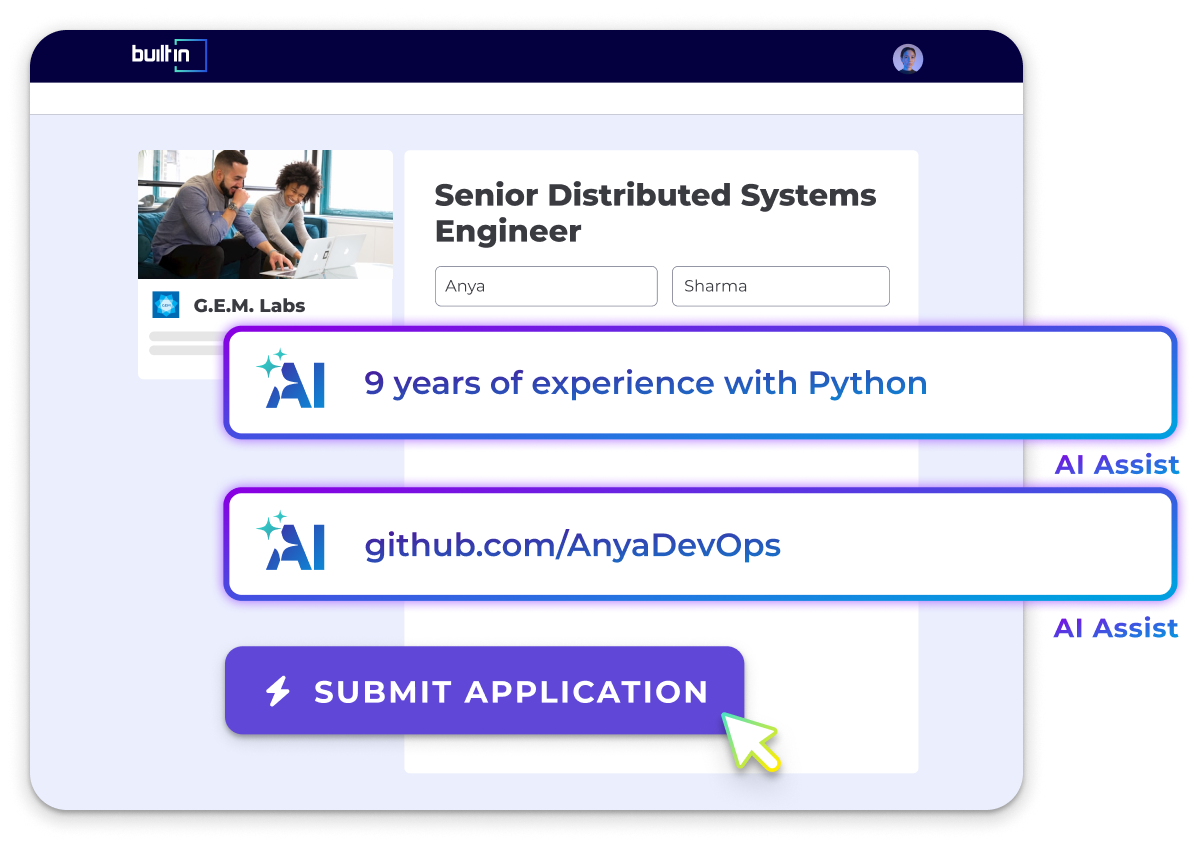
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Build and operate AI infrastructure systems, including telemetry pipelines, observability dashboards, incident-management automation, hardware and software catalogs, service ownership data models, and self-service discovery tools. Lead cross-functional infrastructure initiatives and develop AI-assisted operational tooling. The role requires production software and infrastructure expertise, programming experience, and the ability to improve reliability, visibility, incident response, and operational efficiency across NVIDIA GPU cloud environments.
Top Skills:
Ai Agent FrameworksConfiguration Management Databases (Cmdb)GoJavaMachine Learning ModelsObservability PlatformsPythonSaas Incident-Management ToolsTypescript
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Design and operate large-scale infrastructure supporting GPU- and CPU-based EDA workloads. Build automation for provisioning, configuration, deployment, lifecycle management, monitoring, health remediation, cluster enrollment, and recovery across Linux compute fleets. Integrate services with schedulers, infrastructure systems, and observability platforms. Participate in incident response, root-cause analysis, capacity planning, and reliability improvements while collaborating with EDA, networking, storage, and hardware teams.
Top Skills:
Bright Cluster ManagerCluster SchedulingCpu InfrastructureDistributed SystemsEdaFirmwareGoGpu InfrastructureKubernetesLinuxLsfNetworkingObservabilityPythonSlurmStorage
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Designs and deploys large-scale AI and HPC GPU cloud infrastructure for NVIDIA Cloud Partners. Serves as the primary technical advisor across solution design, development, integration, production, debugging, and customer adoption. Builds proof-of-concepts, integrates AI software stacks, libraries, frameworks, and models, and delivers technical presentations and workshops. Partners with engineering, product, sales, and business teams to secure opportunities, guide product strategy, and support complex customer engagements throughout the lifecycle.
Top Skills:
AWSBase Command ManagerDcgmDeep Learning FrameworksDistributed Cloud ArchitecturesFoundation ModelsGoogle Cloud PlatformGpu Cloud InfrastructureHybrid Cloud InfrastructureKubernetesLarge Language ModelsLoad BalancingAzureMlopsNcclNemo RetrieverNvidia Cuda-XNvidia DynamoNvidia GpusNvidia Mission ControlNvidia Nemo FrameworkNvidia NemotronNvidia Triton Inference ServerPythonPyTorchSlurmTensorFlowTensorrtTensorrt-LlmUfm
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Develop and deploy deep learning models and petabyte-scale multimodal data curation pipelines for foundation-model training. Responsibilities include document extraction, OCR, layout and table analysis, deduplication, distributed processing, dataset and metric development, experimentation, production scaling, and deployment through NVIDIA Inference Microservices. The role also involves publishing research, creating technical documentation, communicating findings, and mentoring team members.
Top Skills:
SparkDaskGpu ClustersNvidia Inference Microservices (Nims)OcrPythonPyTorchRay
Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Lead NVIDIA’s RL post-training frameworks strategy and engineering ecosystem across distributed training, inference, rollout, evaluation, orchestration, and NVIDIA platforms. Build and manage globally distributed teams, prioritize upstream and internal investments, establish benchmarks and execution metrics, and drive reliable open-source integrations. Partner with research, product, hardware, CUDA, networking, and external communities to scale reinforcement learning workloads across GPUs and heterogeneous systems.
Top Skills:
CudaCudnnDistributed SystemsDpoGrpoHigh-Performance ComputingKubernetesMegatron-CoreMilesMonarchNcclNemoNemo-AlignerNixlNsightNvidia GpusOpen-Source SoftwareOpenrlhfPpoRayReinforcement LearningReward ModelingRlhfSglangSkyrlSlimeSlurmTensorrt-LlmTorchtitanTransformer EngineVerl

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.

Popular Seattle, WA Job Searches
Tech Jobs & Startup Jobs in Seattle
Remote Jobs in Seattle
Hybrid Jobs in Seattle
.NET Developer Jobs in Seattle
Account Executive (AE) Jobs in Seattle
Account Manager (AM) Jobs in Seattle
Accounting Jobs in Seattle
Accounting Manager Jobs in Seattle
AI Jobs in Seattle
Analysis Reporting Jobs in Seattle
Analyst Jobs in Seattle
Analytics Jobs in Seattle
Android Developer Jobs in Seattle
AWS Engineer Jobs in Seattle
Biotech Jobs in Seattle
Business Analyst Jobs in Seattle
Business Intelligence Jobs in Seattle
C# Jobs in Seattle
C++ Jobs in Seattle
Communications Jobs in Seattle
Content Jobs in Seattle
Customer Success Jobs in Seattle
Customer Success Manager Jobs in Seattle
Cyber Security Jobs in Seattle
Data & Analytics Jobs in Seattle
Data Analyst Jobs in Seattle
Data Engineer Jobs in Seattle
Data Management Jobs in Seattle
Data Science Jobs in Seattle
DevOps Jobs in Seattle
Engineering Manager Jobs in Seattle
Executive Assistant Jobs in Seattle
Finance Jobs in Seattle
Finance Manager Jobs in Seattle
Financial Analyst Jobs in Seattle
Front End Developer Jobs in Seattle
Front End Developer Jobs in Seattle
Golang Jobs in Seattle
Hardware Engineer Jobs in Seattle
HR Jobs in Seattle
HR Manager Jobs in Seattle
Internships in Seattle
iOS Developer Jobs in Seattle
IT Jobs in Seattle
Java Developer Jobs in Seattle
Javascript Jobs in Seattle
Legal Jobs in Seattle
Linux Jobs in Seattle
Machine Learning Engineer Jobs in Seattle
Machine Learning Jobs in Seattle
Manufacturing Engineer Jobs in Seattle
Marketing Jobs in Seattle
Marketing Manager Jobs in Seattle
Mechanical Design Engineer Jobs in Seattle
Mechanical Engineer Jobs in Seattle
Office Manager Jobs in Seattle
Operations Jobs in Seattle
Operations Manager Jobs in Seattle
PHP Developer Jobs in Seattle
Product Designer Jobs in Seattle
Product Manager Jobs in Seattle
Product Marketing Manager Jobs in Seattle
Program Manager Jobs in Seattle
Project Management Jobs in Seattle
Python Jobs in Seattle
QA Jobs in Seattle
Recruiter Jobs in Seattle
Research Analyst Jobs in Seattle
Research Jobs in Seattle
Robotics Engineering Jobs in Seattle
Robotics Jobs in Seattle
Ruby Jobs in Seattle
Sales Development Jobs in Seattle
Sales Engineer Jobs in Seattle
Sales Jobs in Seattle
Sales Leadership Jobs in Seattle
Sales Manager Jobs in Seattle
Sales Operations Jobs in Seattle
Sales Representative Jobs in Seattle
Salesforce Developer Jobs in Seattle
Scala Jobs in Seattle
Security Engineer Jobs in Seattle
Social Media Jobs in Seattle
Software Development Manager Jobs in Seattle
Software Engineer Jobs in Seattle
Systems Engineer Jobs in Seattle
Tax Manager Jobs in Seattle
Tech Support Jobs in Seattle
Technical Program Manager Jobs in Seattle
UX Designer Jobs in Seattle
UX Researcher Jobs in Seattle
Web Developer Jobs in Seattle
Writer Jobs in Seattle
All Filters
Total selected ()
No Results
No Results
